Online BigData Certification Course
70 hrs online + 45 hrs videos
The course is designed specifically for students and working professionals:
- Give a jump start to your career in Big Data.
- Provide you with necessary skills required to move from novice level to pro level.
- Learn Leading Tools like Apache Spark, Python, ML & more via Projects & Case Studies.
- Learn to structure and interpret data of your domain.
- Make you industry ready.
Next Batch starts: Dec 05, 2021
Limited no. of seats available
Duration: 2 Month
55 Hours / week-end sessions
Mode: Instructor Led Online
Class Format
DETAILED SYLLABUS
Overview of Hadoop & Spark
- Genesis of Spark
- Hadoop – HDFS, YARN, Map-Reduce
- Distributed Storage
- Limitations of Hadoop
- Need of Spark and its Advantages
COURSE DURATION
3 Hours
Understanding Spark
-
The Spark Ecosystem
-
Spark Design Philosophy
-
Distributed Computing & Spark Architecture
-
Role of Driver Manager, Executors, Cluster Manager in Spark
-
Setting up Spark Environment on Windows
COURSE DURATION
- 04 Hours
Getting Started with PySpark Programming
- Spark Session and Spark Context
- Spark WebUI
- Creating our first RDD
- Understanding important concepts in PySpark
- DAG
- Lineage
- Transformations
- Actions
- Partitions
- Lazy Evaluation
- Functional Programming
COURSE DURATION
- 08 Hours
Understanding RDDs
- Understanding RDD Characteristics
- Resilient
- Distributed
- Fault Tolerant
- Transformation Functions
- map()
- filter()
- flatmap()
- sample()
- join()
- repartition()
- coalesce()
- Lambda Function
- Actions
- take(),
- top(),
- collect(),
- reduce(),
- reduceByKey(),
- count()
- Understanding Fine Grained & Coarse Grained Transformations
- Word Cloud Example
COURSE DURATION
- 10 Hours
Understanding DataFrames
- DataFrame vs RDD
- PySpark DataFrame vs Pandas DataFrame
- Creating Spark SQL DataFrame
- Importing Data from File System, Database, HDFS
- Working with JSON, CSV, and Parquet File Formats
- Defining Schema using both StructField and SQL DDL approach
Data Persistence – persist() & cache() - Repartitioning Data Frame
- Exporting DataFrame to File System in .csv, .parquet, and .json file formats
COURSE DURATION
14 Hours
DataFrame Data Manipulation
- Creating / Dropping columns, Filtering Rows
- Sorting and Merging Data
- Broadcast Join vs Sort-Merge Join
- Data Aggregation – Group By
- Window Functions
- rank()
- dense_rank()
- row_number()
- ntile()
- lag()
- lead()
- first_value()
- last_value()
- Stock Market Analysis Example
- Using Spark SQL – SQL approach of Data Manipulation in PySpark
- User Defined Functions – UDF
Stock Market Analysis
COURSE DURATION
- 16 Hours
Talk to us
+91 89396 94874
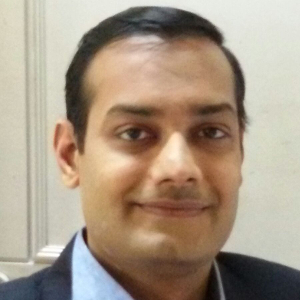
Rajesh Jakhotia
Instructor
Rajesh is an Analytics Professional with 20+ years of experience. He started his analytics career with Fractal Analytics in year 2003. He is an Adjunct Faculty at Great Learning & Gust Faculty at Analytics Vidhya.
His past work experience includes working with Fractal Analytics, Sutherland Global Services, Hansa Customer Equity and Positive Integers providing Analytics Consultancy for some of the marquee Indian Banks & NBFCs like HDFC Bank, Axis Bank, Kotak Mahindra Bank, India Infoline.
His expertise includes building Machine Learning Models for Risk Management and Marketing. He has worked on tools like Python, R, SAS, SQL.
He successfully completed the Senior Management Program from IIM-C. He is an Engineering Graduate from V.J.T.I, Mumbai University. He is also Oracle Certified Associated and Project Management Program certified from PMI.
More Capstone Projects
An IT company has more than 100000 employees and have a very high attrition rate. The business environment is very competitive, and the cost of replacement is much higher than the cost of retaining an existing employee. If a skilled employee resigns the replacement involves cost of hiring and training. There is also some loss of efficiency till the new employee comes to speed.
The IT company sample data has been provided. HR Department of the company is looking for an attrition model that can help identify the employees who are likely to resign. Based on the model, HR will build an employee retention strategy and they have estimated that they can save more than Rs. 100 Million if they reduce the attrition rate by 0.5%.
As a Data Scientist our goal is to build Employee Attrition Model
A bank in Middle East would like to build Credit Default Model for their Home Loans portfolio. The model is an Application Scorecard for Home Loans and it will be used to evaluate credit worthiness of future customers applying for home loans.
The data of about 20000 loans customer with their default status has been provided. The data is a mix of expats and locals. The demographic details, income details and loan related parameters have been provided.
You have been assigned the task of building Application Scorecard for Home Loans using Logistic Regression Model. The probability of default as predicted by the model has to be converted into credit score such that a total score of 600 points corresponds to good/bad odds of 50 to 1 and an increase of the score of 20 points corresponds to a doubling of the good/bad odds.
MyBank wish to develop Direct Marketing channel by cross-selling various banking products and services to their existing customer base. The bank executed a pilot campaign to sell personal loans to their deposit account holders. The campaign offer was communicated to the customers through email, sms, and direct mailers.
The customers were incentivized to respond by giving the loan at 1% rate lower than market rate along with the processing fee waiver if the customer availed the loan within 15 days time period.
The demographics and behavioural variables along with responder / non-responder of the campaign has been provided. You have been assigned the task to build a Predictive Model to find profitable segments for cross-selling personal loans. Along with the model you must provide the model implementation and deployment strategy for future campaigns.
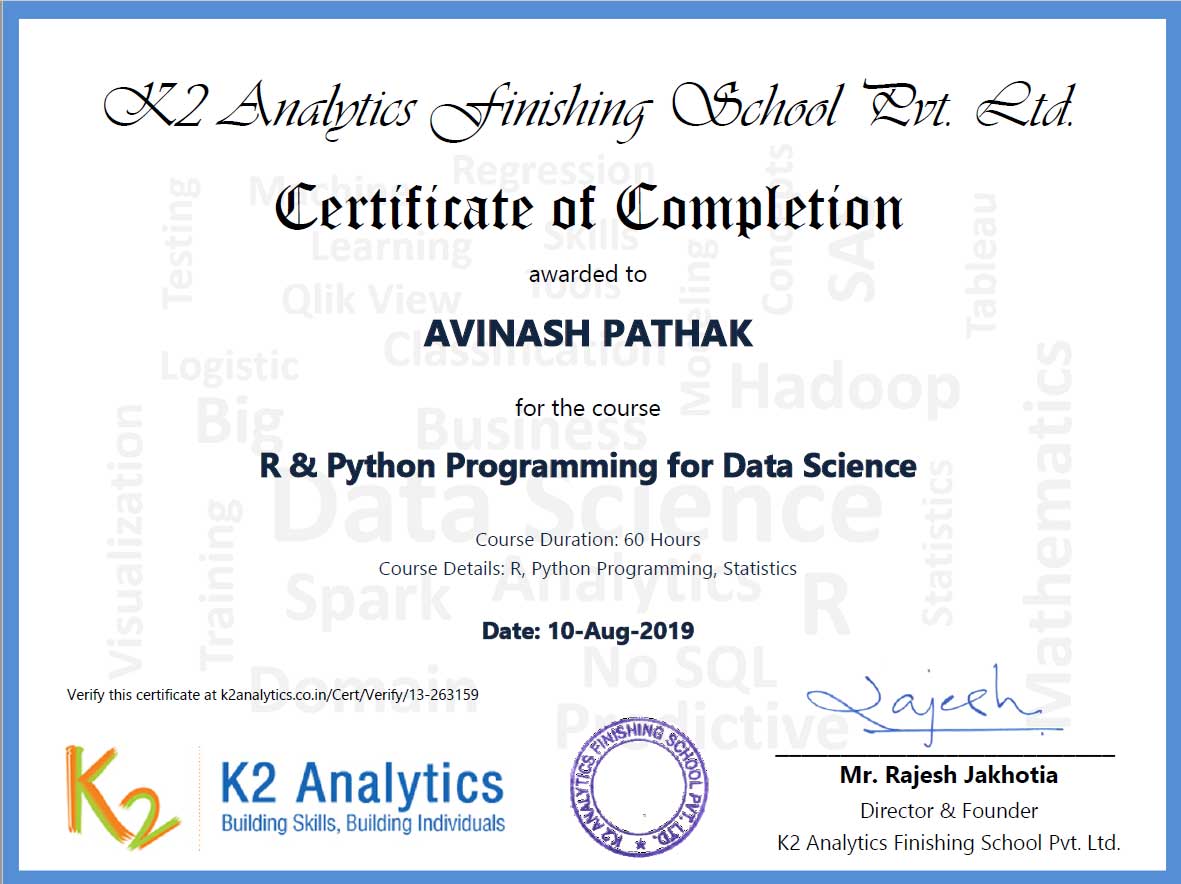
Sample E-Certificate
Testimonials
We had invited Mr Rajesh from K2 Analytics to conduct a workshop on Machine Learning and R Programming. The workshop was very well appreciated by all the participants. We are thankful for your time and the knowledge shared with us. I would like to rate the training 5 out of 5 for the training quality, content and the case-study way of explaining the topic which struck the right chord with the audience who were from the First Year and Second Year of Engineering. Thanks, k2analytics.
Within 2 months of Machine Learning course commencement, my perspective of looking at data had changed drastically. It helped me to present my existing reports and dashboards with insightful information. It is truly said “If you don’t know the business, data can teach you.” Complex terms were explained in a very elegant and simpler way to make it very easy to understand. The industry experience regularly shared by the trainer helps a lot. Many thanks to K2 Analytics!
I think joining K2 has been one of the best decision i have made in my career. Rajesh sir is very passionate instructor with immense knowledge in most demanding domain of this era and has great teaching skills, he keeps it simple for us to understand any complex concepts. I joined here with level-0 analytics skills but now after machine learning with R session i think I am ready to transform myself into analytics domain. I would highly recommend K2 Analytics to those who aspire to make career in Analytics domain.
3000+ STUDENTS POSITIVELY IMPACTED
100+ HOURS OF TRAINING CONTENT
FAQ’s
What is the median salary of a Data Scientist in India ?
According to the report, the median salary being offered for analytics jobs in India is INR 11.5 lakhs/annum.
What is Data Science ?
Data science is a multi-disciplinary field that uses scientific methods, processes, algorithms, and systems to extract knowledge and insights from structured and unstructured data.
Is Data Science a good career option ?
A Big YES, Data Science is a good career option. The U.S. Bureau of Labor Statistics reports that the rise of data science needs will create 11.5M job openings by 2026. According to IBM, the demand for Data Scientists will increase up to 28% by the year 2020.
Best way to learn Data Science as a beginner ?
Make sure you are guided by an experienced Professional Faculty in DATA SCIENCE.